Type text, dream video.
A two-person research lab training generative video models from scratch.
A cute 3‑D animated baby goat with shaggy gray fur, a fluffy white chin tuft, and stubby curved horns perches on a round wooden stool. Warm golden studio lights bounce off its glossy cherry‑red acoustic guitar as it rhythmically strums with a confident hoof, hind legs dangling. Framed family portraits of other barnyard animals line the cream‑colored walls, a leafy potted ficus sits in the back corner, and dust motes drift through the cozy, sun‑speckled room.
Download model weights →
Linum v2 · 2B params · Apache 2.0
FIELD NOTES
Research, releases, and real-world lessons building generative video.
From our partners · Jun 22, 2026
How Linum built a frontier video model on Crusoe ↗︎
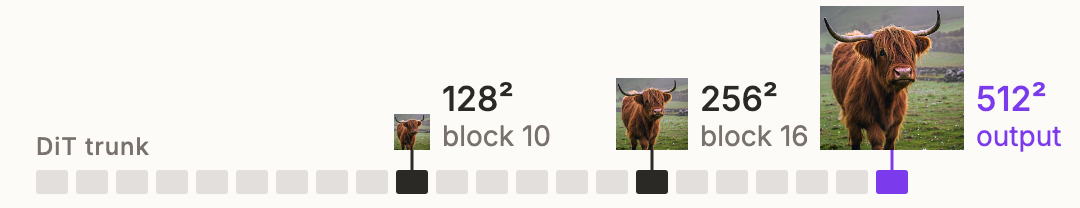
Pyramid-JiT: Low-Res Drafts, High-Res Images
Accelerating convergence in text-to-image with multiresolution prediction
20 min readRoad to Linum v3· Issue 03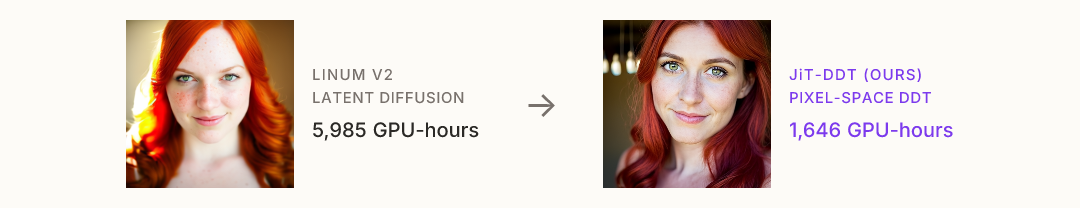
Training Text-to-Image Models 3.6× Faster
Beating latent diffusion models with pixel-space encoder-decoders
40 min readRoad to Linum v3· Issue 02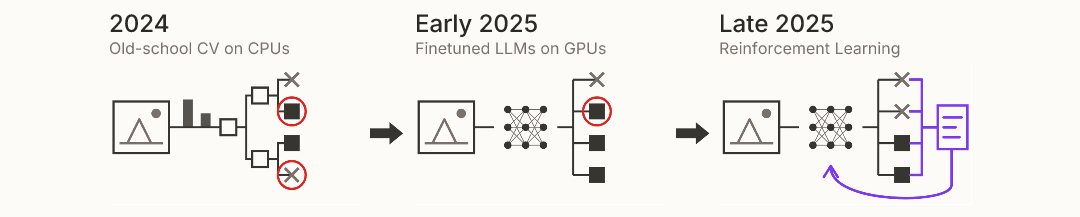
Data Filtering for Generative Video Pre-training
Getting video models to learn better, faster
22 min readRoad to Linum v3· Issue 01